The operations handbook: how do you know your AI feature still works two months later?
The feature shipped, the demo worked, the team celebrated. Eight weeks later the model provider silently rolled a new version, your customers’ dialect shifted with a new season, and a colleague added a line to the prompt…
The feature shipped, the demo worked, the team celebrated. Eight weeks later the model provider silently rolled a new version, your customers’ dialect shifted with a new season, and a colleague added a line to the prompt. Nobody knows quality dropped because nobody measures it. This handbook is about measuring.
The principle: prompts are code, and code needs tests
Every change to a prompt, model or tool passes through a fixed eval set before merge. In BrandBoost AI the set is 300 real requests with reference outputs approved by the marketing team. CI rejects the merge if the aggregate score drops by more than two points.
The four layers of measurement
- Deterministic checks: is the output valid JSON? Does it contain the required fields? Is the length within limits? Cheap, fast, and catches 40% of breakages.
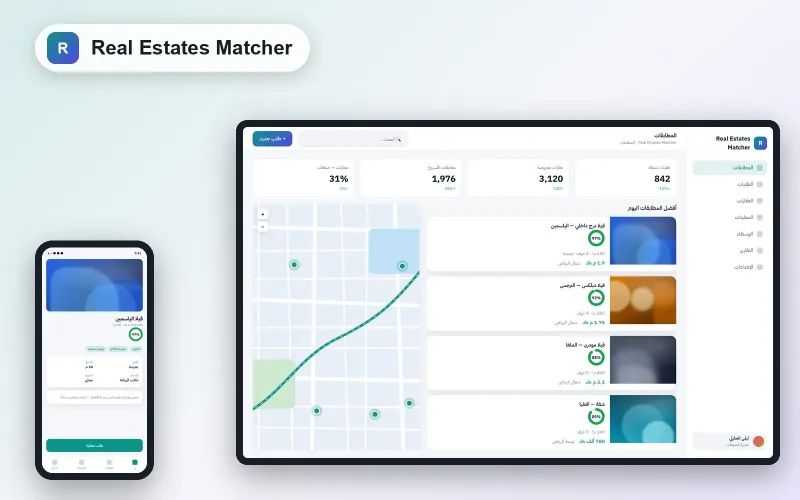
- Domain rules: in Real Estates Matcher the model must never suggest a property outside the seeker’s budget — a simple rule checked programmatically after every generation.
- LLM-as-judge: a second model grades tone or accuracy against a written rubric. Useful, but calibrated regularly against human judgement.
- Sampled human review: 2% of real outputs weekly, with fixed questions, recorded on the same dashboard.
If you do not have one number describing your AI feature’s quality this week versus last week, you are not operating it; you are hoping.
Monitoring in production
- Full trace per request: model, version, prompt, tools called, latency, cost.
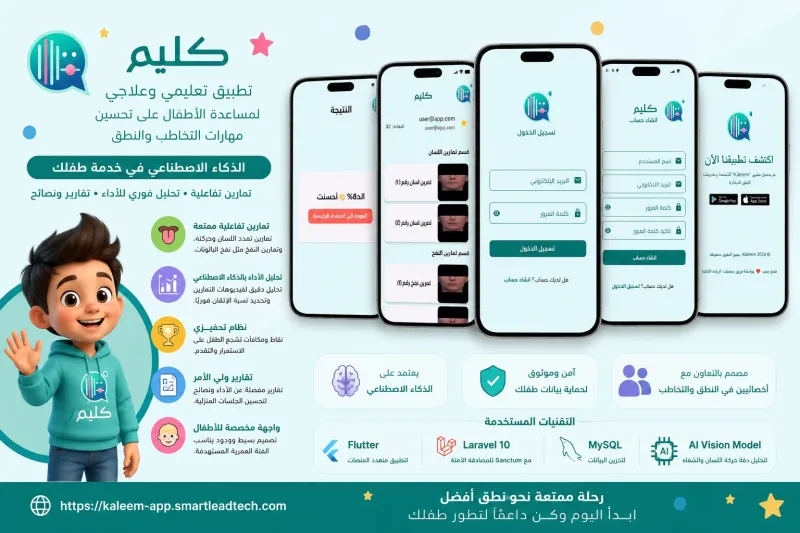
- User-behaviour signals: rephrasing, cancelling, tapping “talk to a human”. In Kaleem we watch the “exercise retry rate” as a signal that a generated sentence sounded unnatural.
- Drift alerts: a shift in average reply length or refusal rate beyond two standard deviations wakes the team.
A short story about silent drift
One month, BrandBoost AI’s cost rose 60% with no change in usage. The cause: a model update made replies a third longer. Without the cost-per-request panel we would have found out on the invoice. We added a max-length domain rule and everything returned to normal within an hour.
Tools you do not need to buy
PostgreSQL for traces, a simple Grafana board, and an evals/ folder in the repo with one command that runs everything. Commercial tools are excellent later; discipline first.